Extended from EasyTune (ICLR 2026).
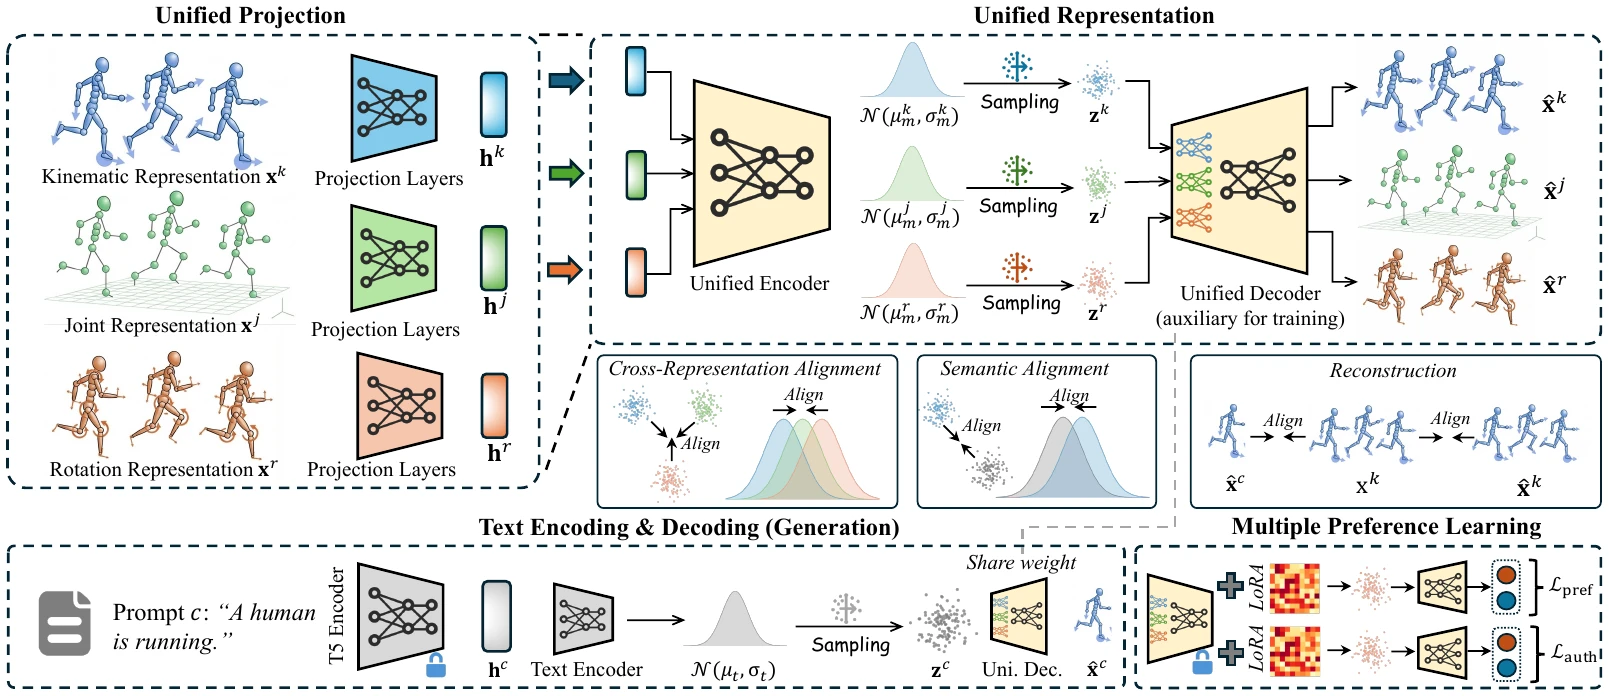
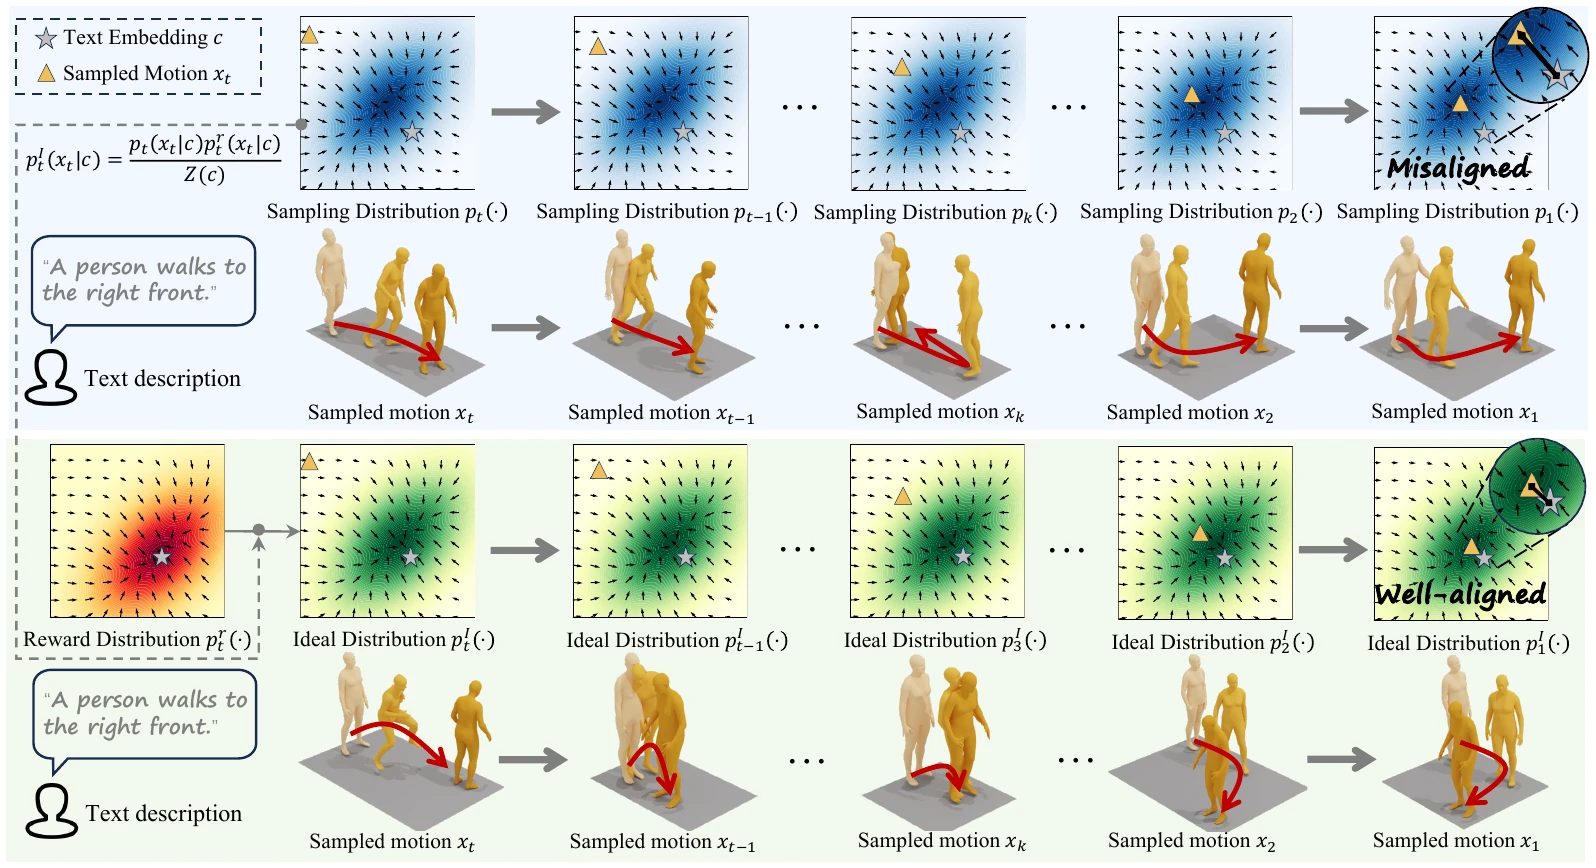
Text-to-motion generation has rapidly advanced with diffusion- and flow-based generative models, yet supervised pre-training remains insufficient to align models with high-level objectives such as semantic consistency, realism, and human preference. However, existing post-training methods have key limitations: (1) they are often designed for a specific motion representation, such as joint- or rotation-based motions, (2) they typically optimize a particular aspect, such as text-motion alignment or human preference, and may compromise other quality factors, and (3) they incur substantial computational overhead, data dependence, and coarse-grained optimization. We present a reinforcement fine-tuning framework that comprises a heterogeneous-representation, multi-dimensional reward model MotionReward and an efficient, fine-grained fine-tuning strategy EasyTune. To obtain a unified semantics representation, MotionReward maps heterogeneous motion representations into a shared semantic embedding space, where the text description serves as an anchor, paving the way for multi-dimensional reward learning. To enhance semantic alignment without additional annotated data, we propose Self-refinement Preference Learning, dynamically mining the preference and refinement itself. For efficient and effective fine-tuning, we identify a key limitation of differentiable-reward methods, the recursive dependence across denoising steps. Motivated by this insight, we propose EasyTune, which fine-tunes diffusion step-wise rather than over the full trajectory, decoupling this dependence and enabling dense, fine-grained, and memory-efficient optimization. Extensive experiments demonstrate strong cross-model and cross-representation generalization, achieving FID 0.132 with 22.10 GB peak memory and saving up to 15.22 GB over DRaFT. Beyond kinematic-based MLD and MDM, it reduces FID by 22.9% on joint-based ACMDM, and achieves a 12.6% R-Precision gain and 23.3% FID improvement on rotation-based HY Motion.
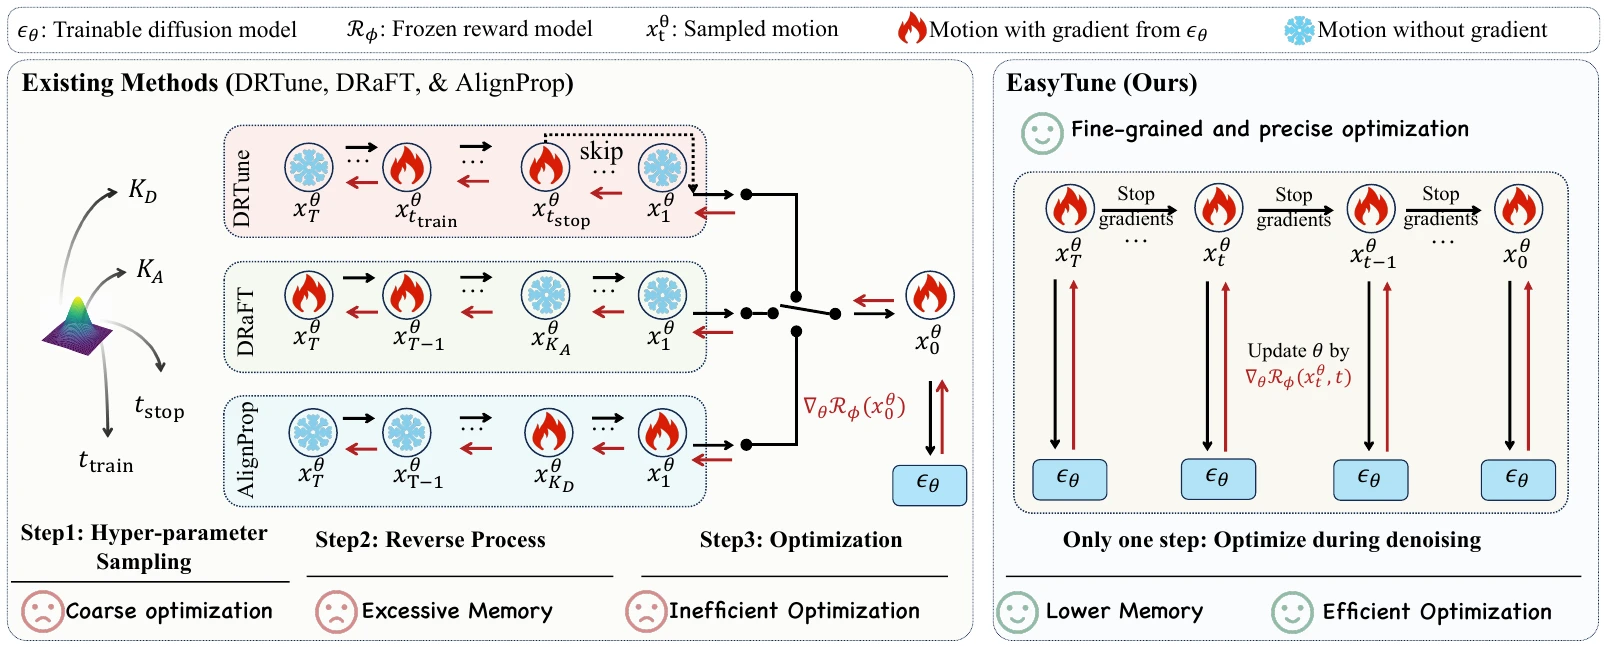 EasyTune: Efficient Step-Aware Fine-Tuning for Diffusion-Based Motion GenerationICLR 2026| International Conference on Learning Representations Poster CCF-ACORE-A*
 Multi-Scale Fuzzy Rough Sets based Anomaly Detection with Multiple AutoencodersUnder Review, 2024