Video anomaly detection (VAD) is a vital yet complex open-set task in computer vision, commonly tackled through reconstruction-based methods. However, these methods struggle with two key limitations: (1) insufficient robustness in open-set scenarios, where unseen normal motions are frequently misclassified as anomalies, and (2) an overemphasis on, but restricted capacity for, local motion reconstruction, which are inherently difficult to capture accurately due to their diversity. To overcome these challenges, we introduce a novel frequency-guided diffusion model with perturbation training. First, we enhance robustness by training a generator to produce perturbed samples, which are similar to normal samples and target the weakness of the reconstruction model. This training paradigm expands the reconstruction domain of the model, improving its generalization to unseen normal motions. Second, to address the overemphasis on motion details, we employ the 2D Discrete Cosine Transform (DCT) to separate high-frequency (local) and low-frequency (global) motion components. By guiding the diffusion model with observed high-frequency information, we prioritize the reconstruction of low-frequency components, enabling more accurate and robust anomaly detection. Extensive experiments on five widely used VAD datasets demonstrate that our approach surpasses state-of-the-art methods.
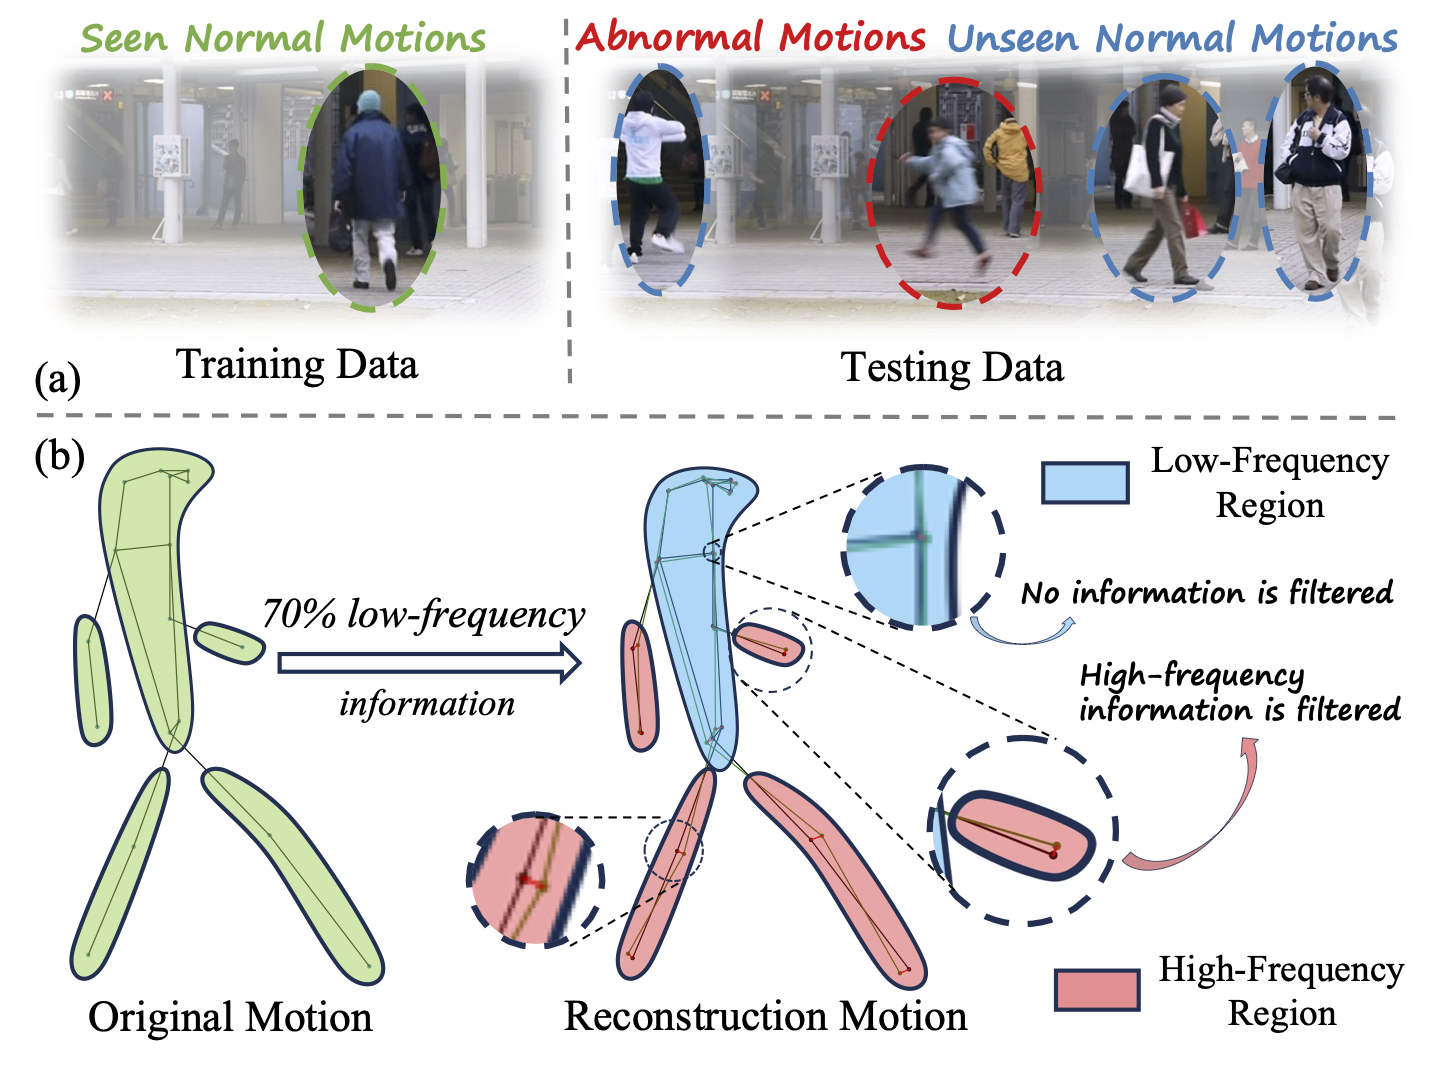
Figure 1. (a) Training data consists of seen normal motions; testing data contains unseen normal and abnormal motions. (b) A motion retaining only 70% low-frequency information remains similar to the original in global structure.
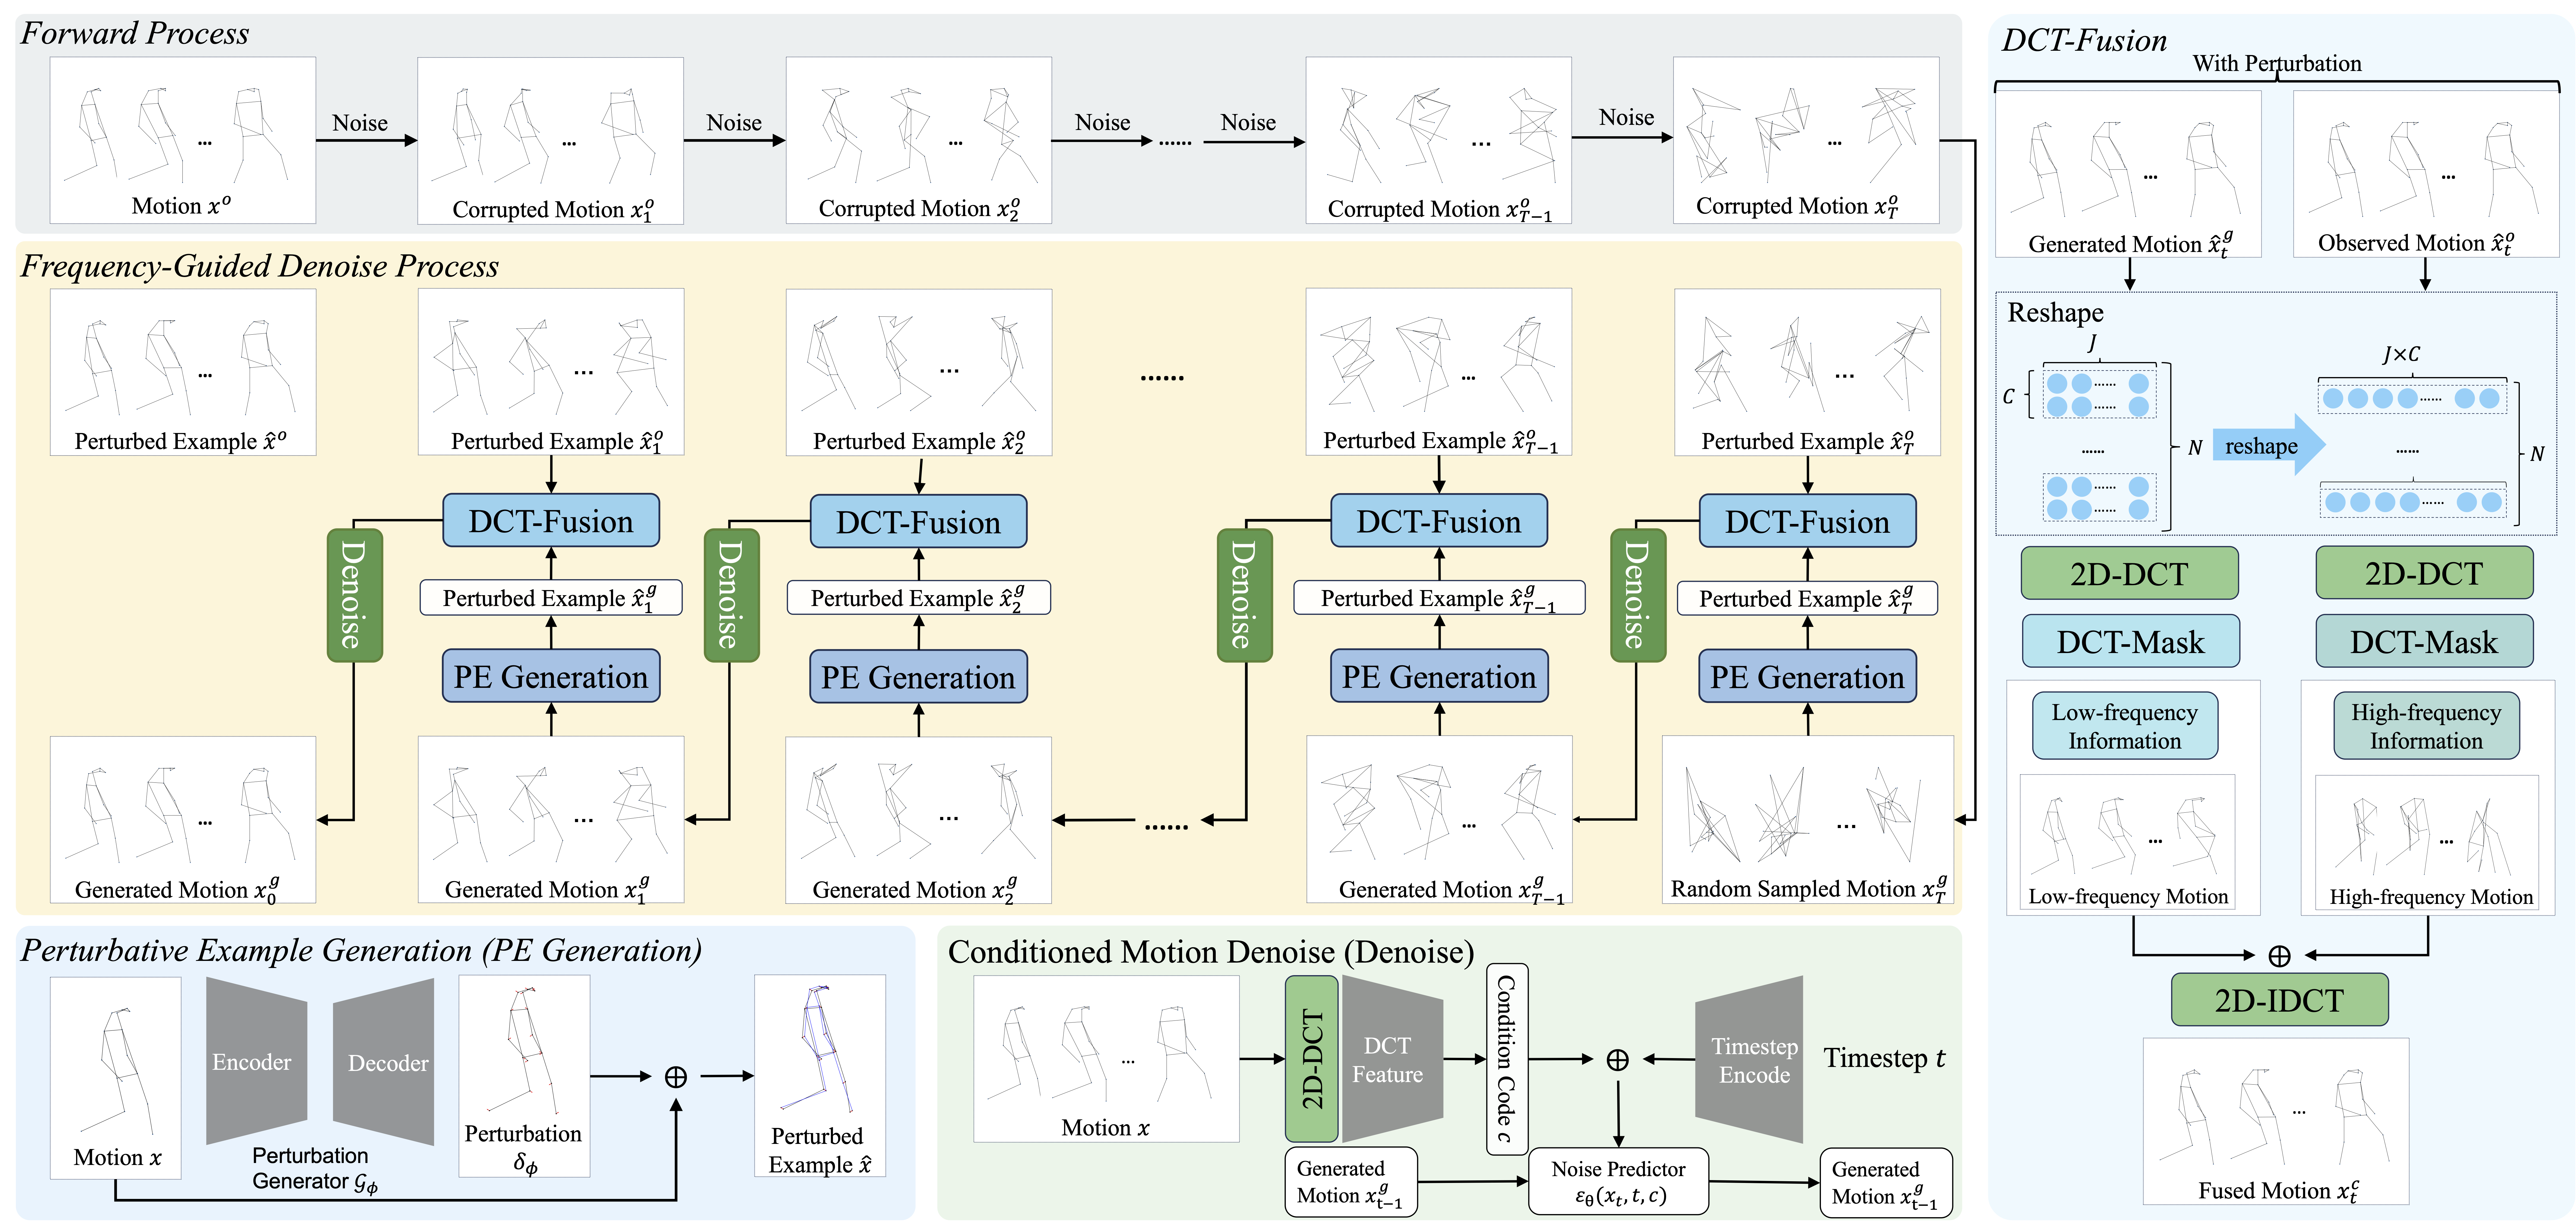
Figure 2. Overview of FG-Diff. Training includes: (1) minimizing MSE to train the noise predictor, and (2) maximizing MSE to train the perturbation generator. During testing, high-frequency information of observed motions and low-frequency information of generated motions are fused.
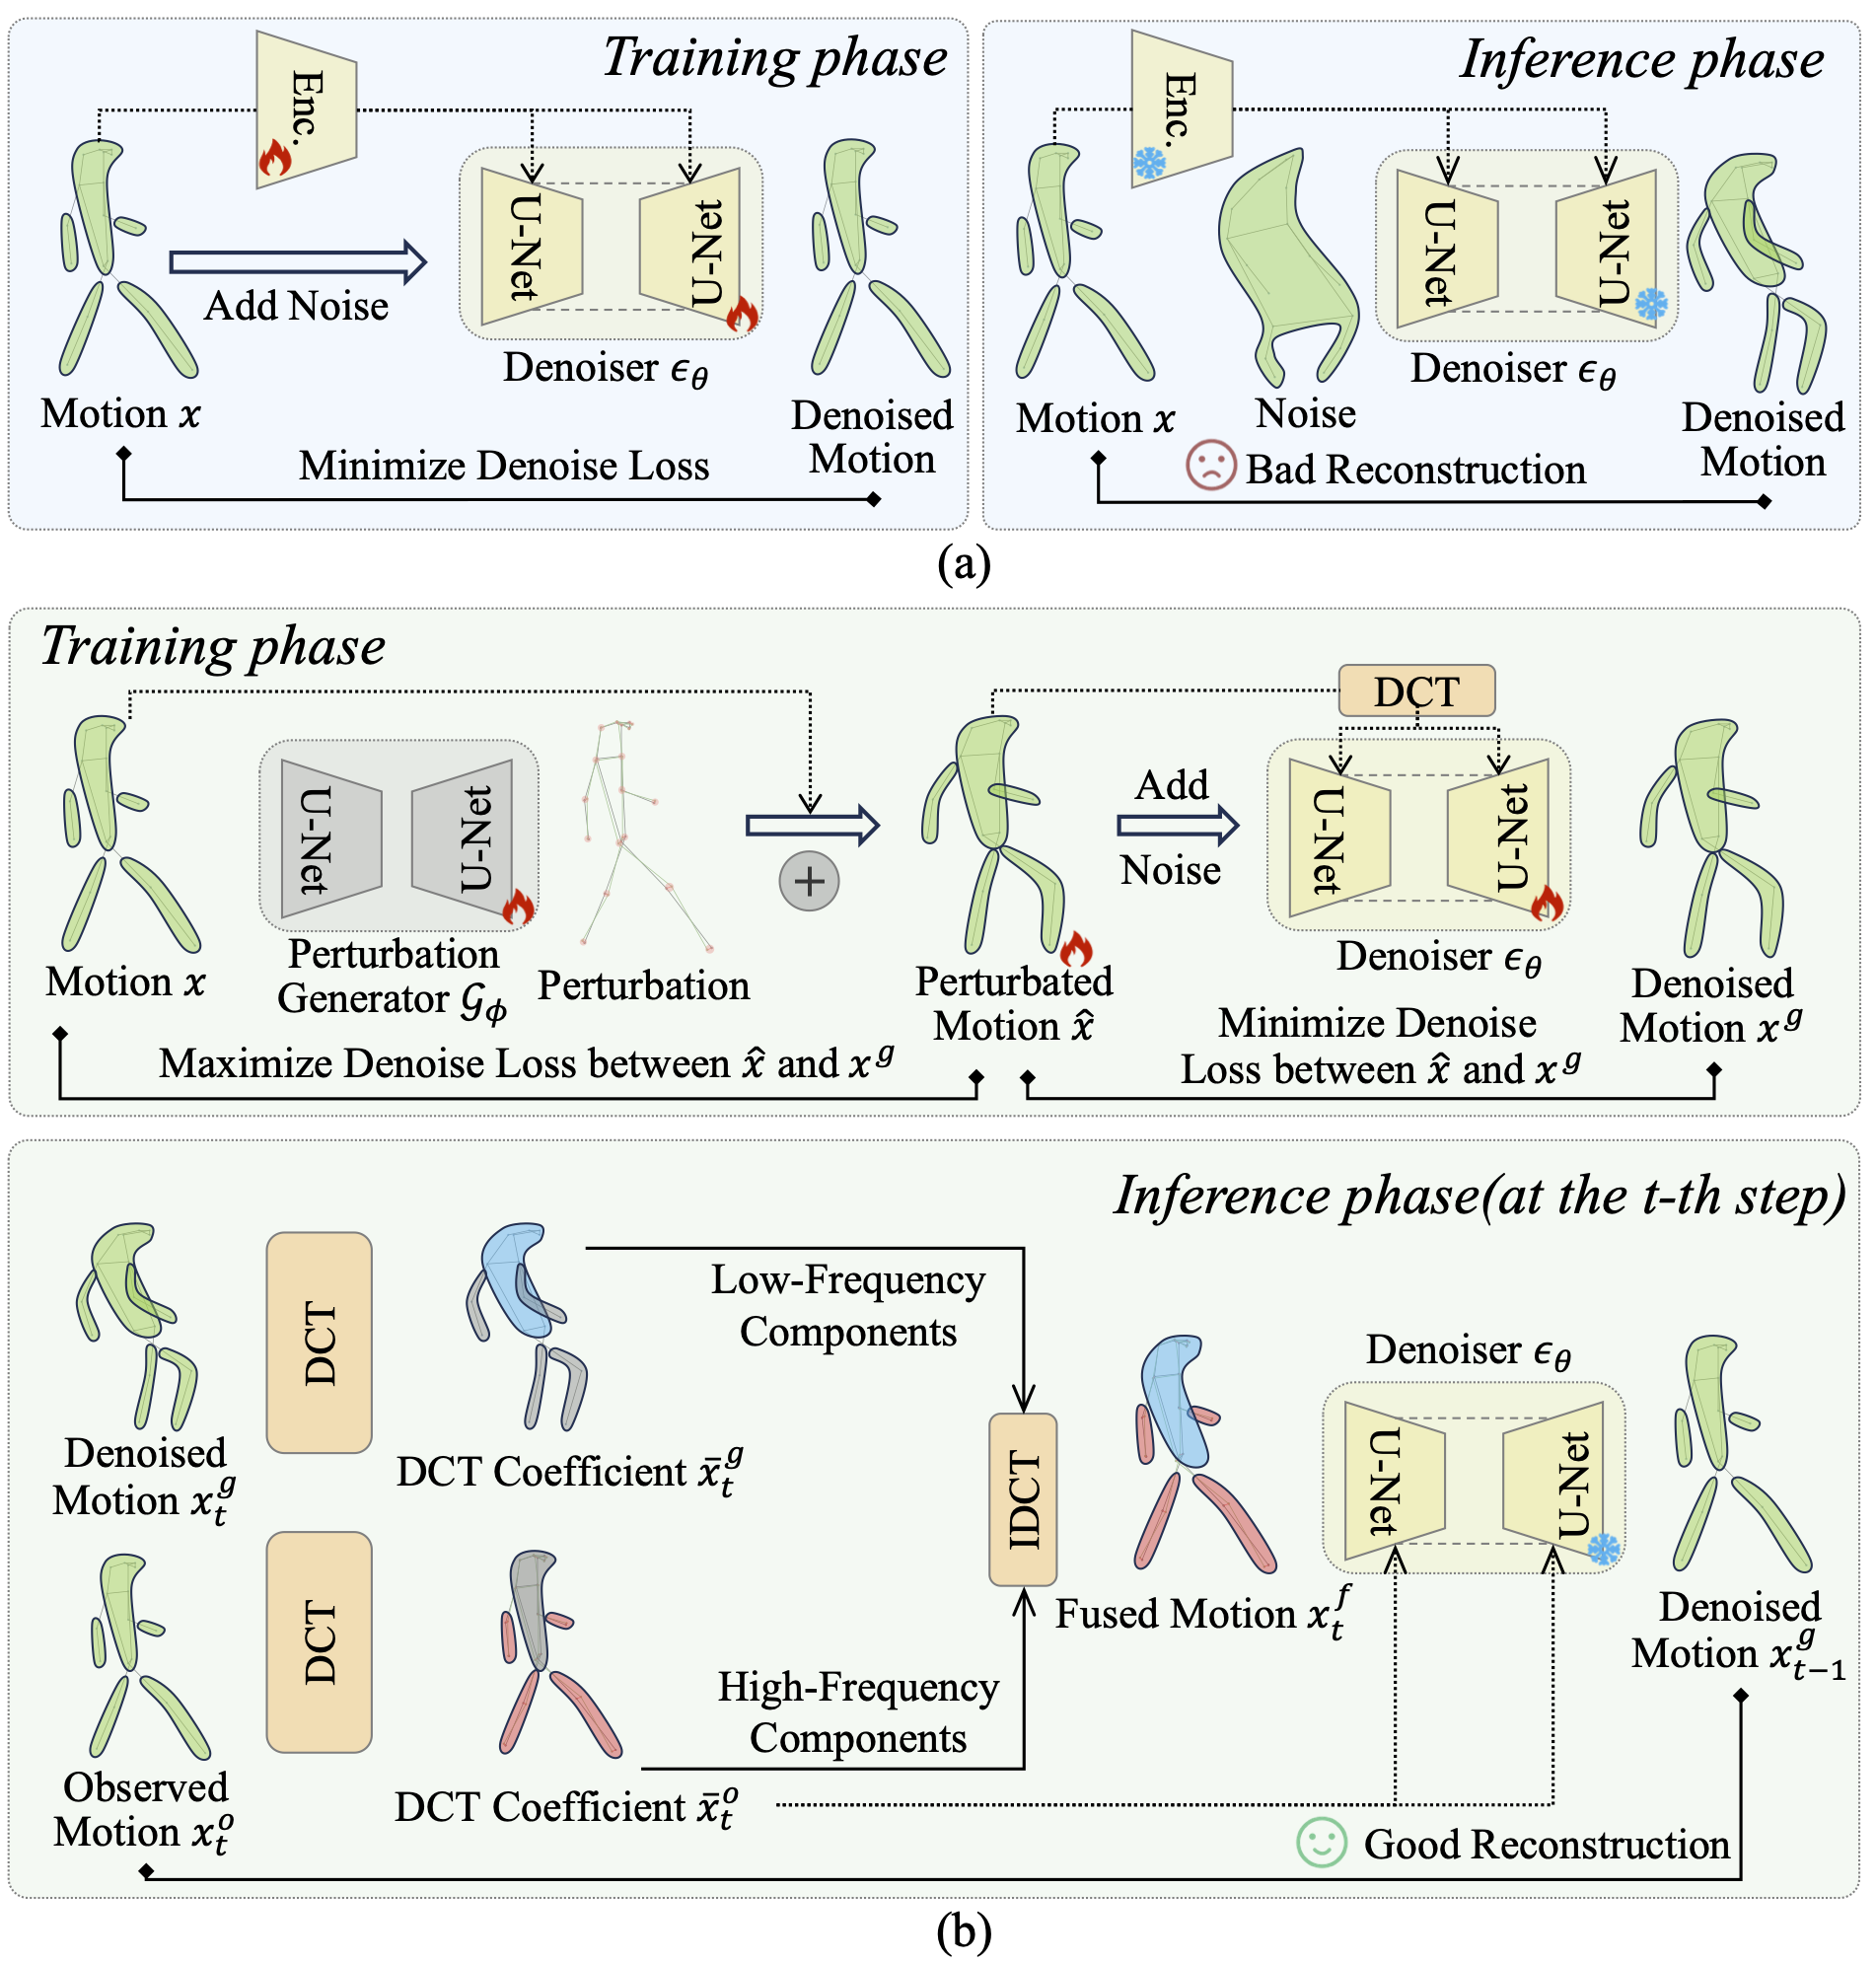
Figure 3. Comparison with existing methods. Training: adversarial training of the perturbation generator and denoiser. Inference: DCT separates motion into global (low-freq) and local (high-freq) components.
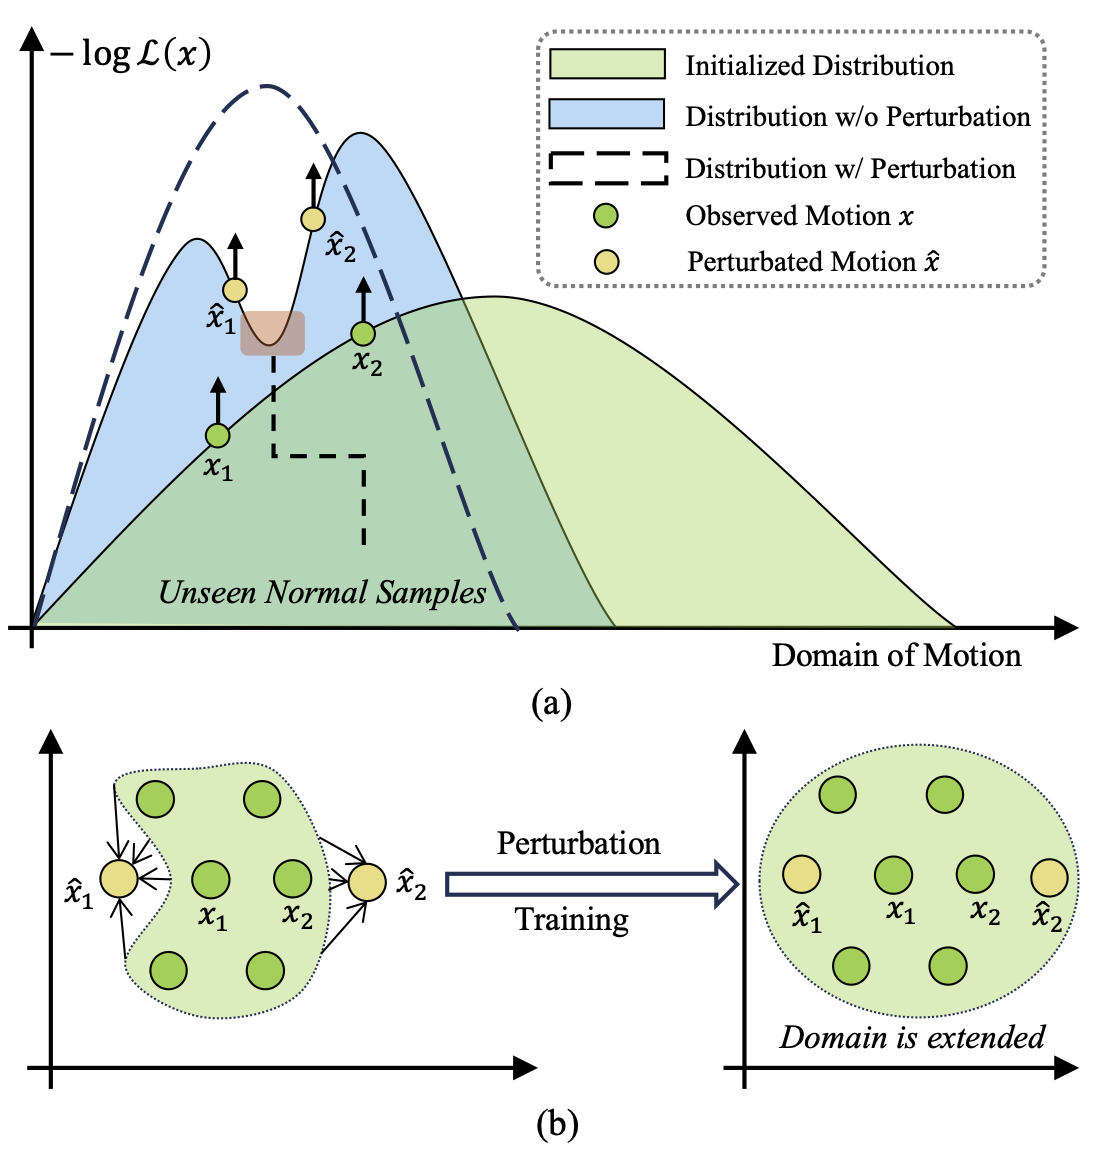
Figure 4. Perturbation training. (a) Green and yellow points denote original and perturbed motions. (b) The reconstruction domain is extended by perturbation training.
| Type | Method | Venue | Modality | Avenue | HR-Ave. | HR-STC | UBnormal | HR-UBn. |
|---|---|---|---|---|---|---|---|---|
| Pred. | MPED-RNN-Pred. | CVPR'19 | Skeleton | - | - | 74.5 | - | - |
| Multi-Time. Pred. | WACV'20 | Skeleton | - | 88.3 | 77.0 | - | - | |
| PoseCVAE | ICPR'21 | Skeleton | - | 87.8 | 75.7 | - | - | |
| AMMC | AAAI'21 | RGB | 86.6 | - | - | - | - | |
| F2PN | T-PAMI'22 | RGB | 85.7 | - | - | - | - | |
| TrajREC-Ftr. | WACV'24 | Skeleton | - | 89.4 | 77.9 | 68.0 | 68.2 | |
| Hybrid | MPED-RNN | CVPR'19 | Skeleton | - | 86.3 | 75.4 | 60.6 | 61.2 |
| sRNN | T-PAMI'21 | RGB | 83.5 | - | - | - | - | |
| MoCoDAD | ICCV'23 | Skeleton | - | 89.0 | 77.6 | 68.3 | 68.4 | |
| Others | GEPC | CVPR'20 | Skeleton | - | 58.1 | 74.8 | 53.4 | 55.2 |
| COSKAD-Hype. | PR'24 | Skeleton | - | 87.3 | 75.6 | 64.9 | 65.5 | |
| COSKAD-Eucli. | PR'24 | Skeleton | - | 87.8 | 77.1 | 65.0 | 63.4 | |
| EVAL | CVPR'23 | RGB | 86.0 | - | - | - | - | |
| OVVAD | CVPR'24 | RGB | 86.5 | - | - | 62.9 | - | |
| Rec. | MPED-RNN-Rec. | CVPR'19 | Skeleton | - | - | 74.4 | - | - |
| TrajREC-Prs. | WACV'24 | Skeleton | - | 86.3 | 73.5 | - | - | |
| TrajREC-Pst. | WACV'24 | Skeleton | - | 87.6 | 75.7 | - | - | |
| ST-PAG | CVPR'24 | RGB | 86.5 | - | - | 58.0 | - | |
| FG-Diff (Ours) | TIP'26 | Skeleton | 88.0 | 90.7 | 78.6 | 68.9 | 69.0 |
| Method | HR-Avenue | HR-STC | HR-UBnormal |
|---|---|---|---|
| Baseline | 87.5 (โ 3.2) | 75.2 (โ 3.4) | 64.4 (โ 4.6) |
| Ours w/o IP | 90.4 (โ 0.3) | 77.4 (โ 1.2) | 68.7 (โ 0.3) |
| Ours w/ double IP | 90.7 (-) | 78.5 (โ 0.1) | 68.6 (โ 0.4) |
| Ours w/o DCT-Mask | 89.9 (โ 0.8) | 78.0 (โ 0.6) | 68.1 (โ 0.9) |
| Ours | 90.7 | 78.6 | 69.0 |
Left: ground truth labels. Right: detection results.
@article{tan2026fgdiff,
title={Frequency-Guided Diffusion Model with Perturbation Training for Skeleton-Based Video Anomaly Detection},
author={Tan, Xiaofeng and Wang, Hongsong and Geng, Xin and Wang, Liang},
journal={IEEE Transactions on Image Processing},
year={2026},
doi={10.1109/TIP.2026.3730816}
}